
New research highlights the pitfalls of inflated accuracy reports in EEG-based ADHD diagnostics, emphasising the importance of subject-wise validation for reliable clinical tools.
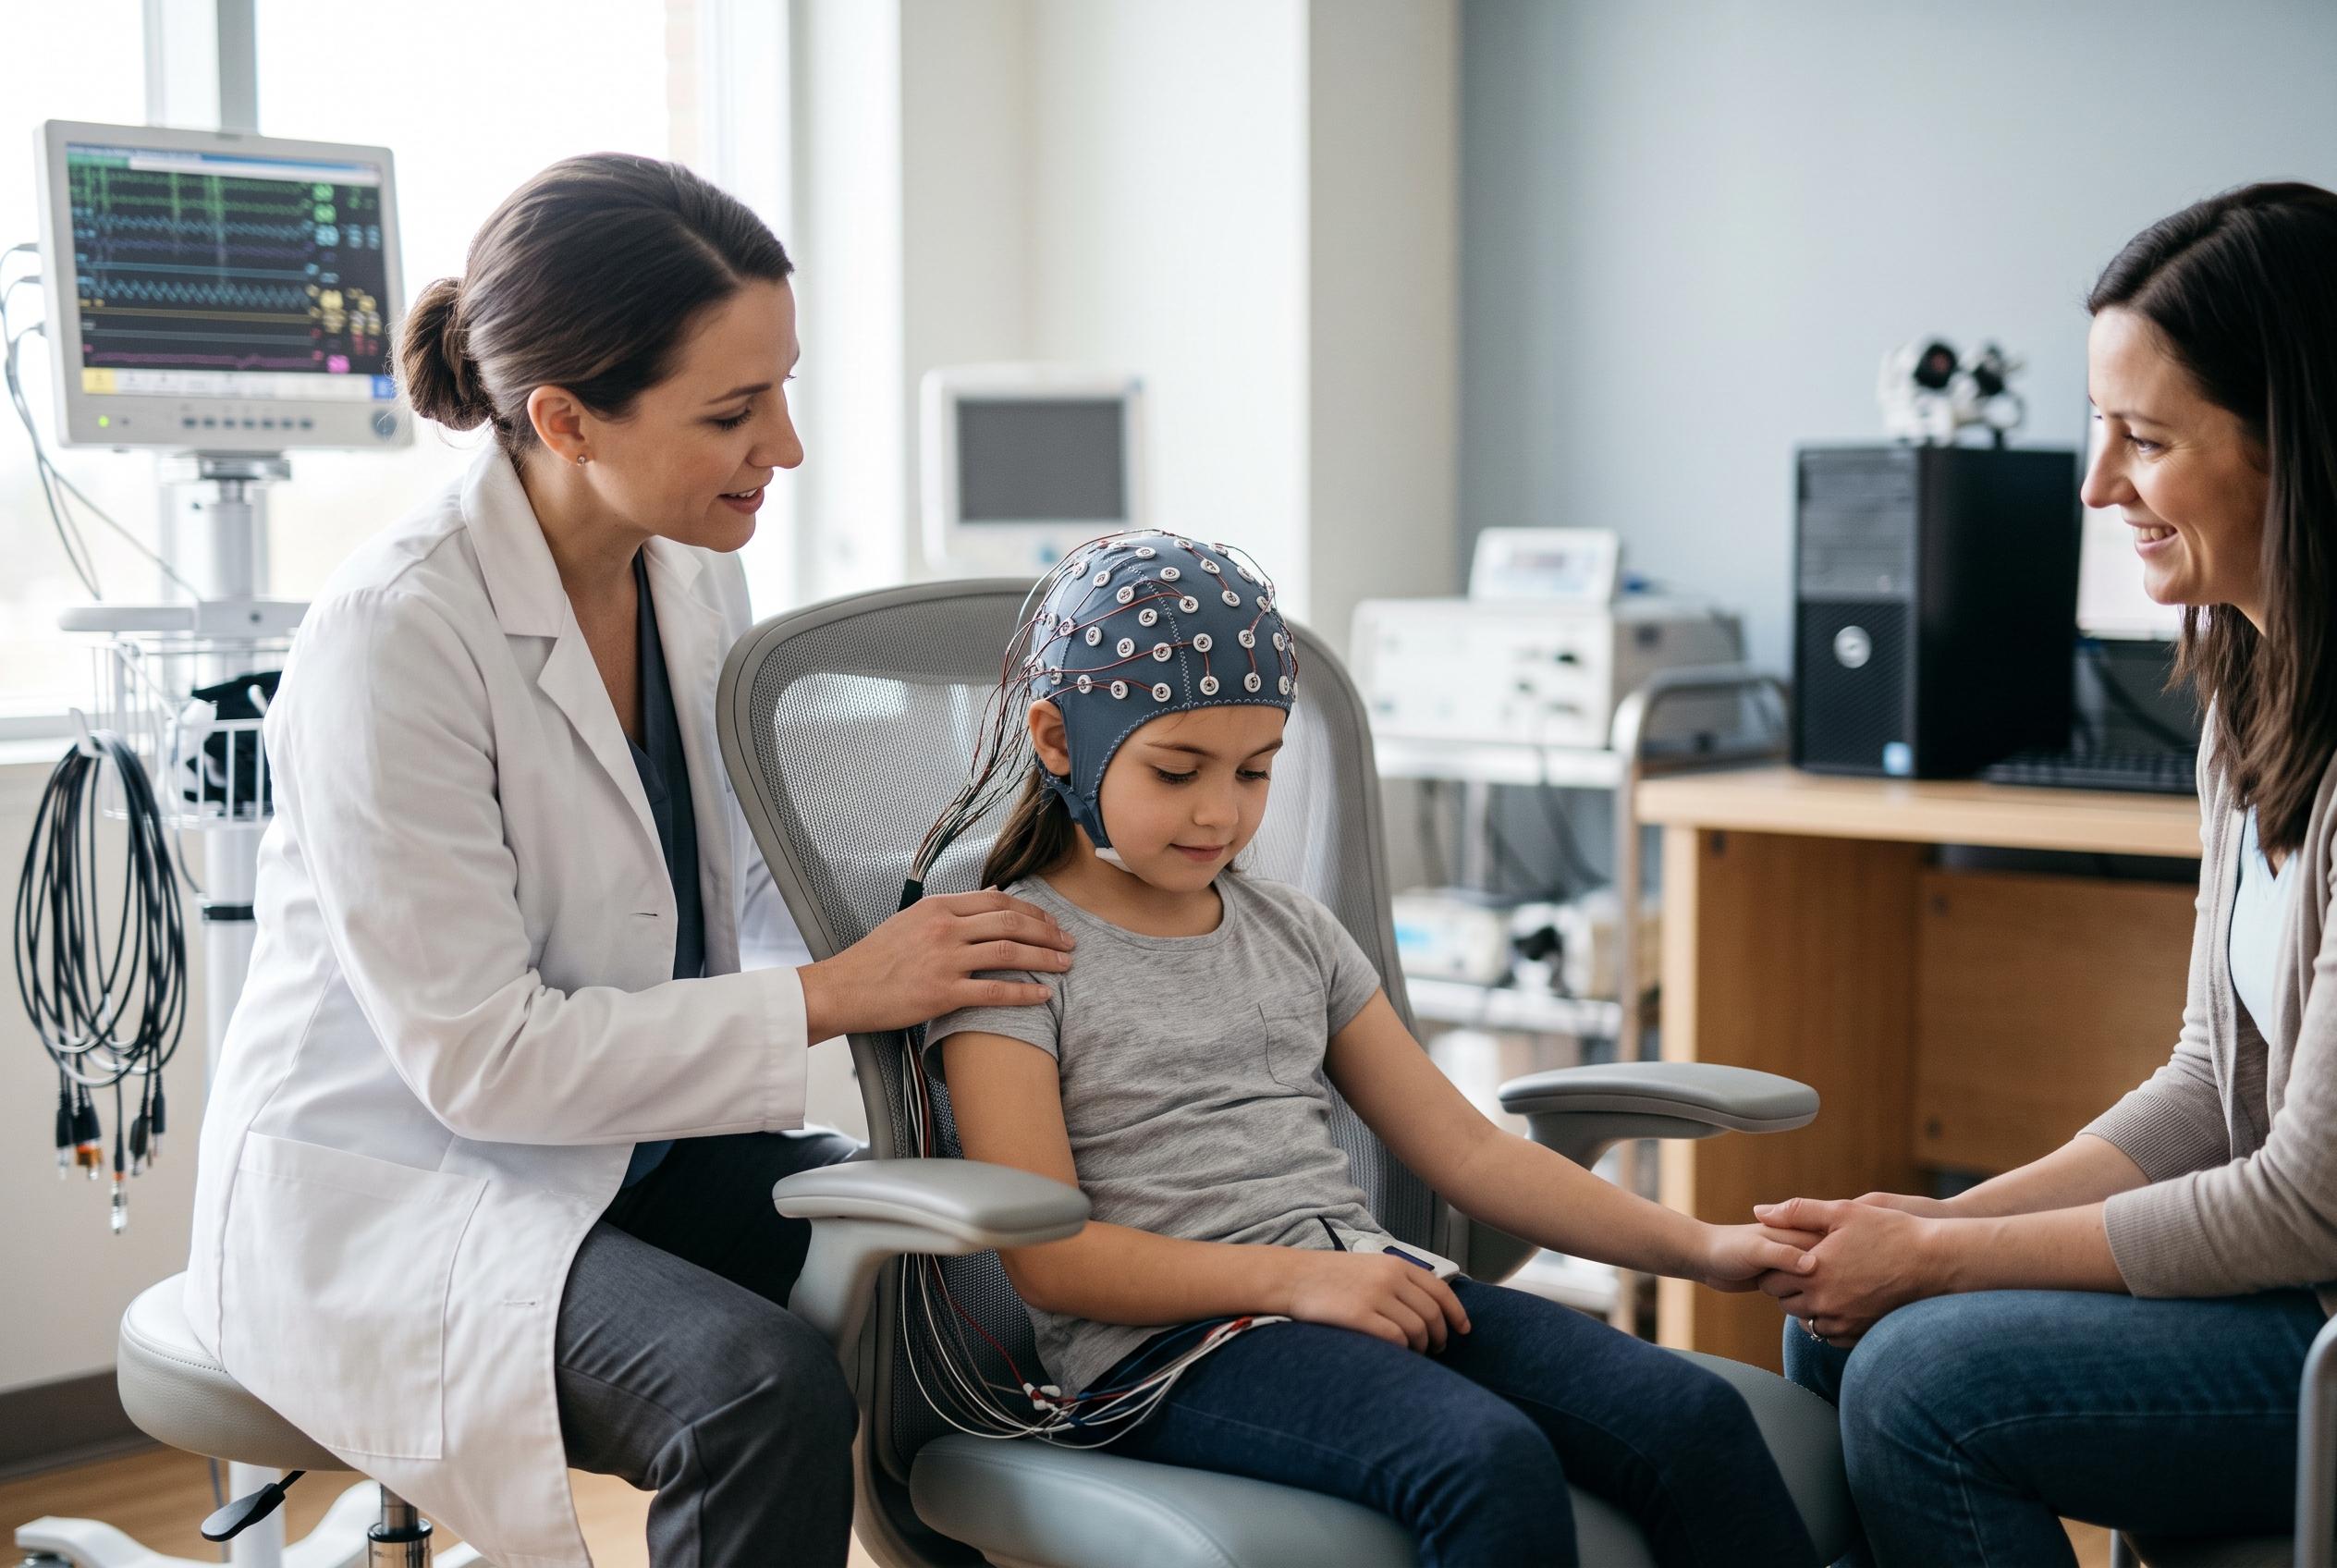
A new Frontiers in Neuroscience study adds fresh weight to a growing warning in EEG research: some of the most eye-catching ADHD screening results may be far less robust than they appear. Working with a publicly available dataset of 121 children, the authors found that models built on hand-crafted power spectral density features could reach about 90% accuracy when the data were split by short EEG segments, but performance fell sharply when the test set contained completely unseen participants. By contrast, a compact convolutional neural network trained directly on raw EEG lost only a small amount of accuracy under the stricter evaluation, suggesting that the gap between impressive laboratory numbers and real-world generalisation can be wide. The paper argues that subject-wise validation, not epoch-wise splitting, should be treated as the default for translational EEG work.
The difference matters because random windowing can allow the same child’s EEG epochs to appear in both training and testing sets. That creates a form of leakage, in which a model may learn participant-specific quirks rather than features of ADHD itself. Educational material from EEGDash describes this as a common pitfall in decoder evaluation, warning that inflated cross-validation scores often collapse when the model faces new people. The Frontiers paper’s results reflect that concern: the same SVM pipeline that looked highly successful under segment-wise testing dropped by more than 24 percentage points when the authors removed the leakage route.
The study also sits within a broader pattern emerging across the field. A recent PubMed-indexed paper reported that a dual-stream attention-enhanced network achieved 88.4% accuracy under subject-wise cross-validation on the same 121-child cohort, reinforcing the idea that careful participant-level evaluation can still produce useful models, but only when the testing setup is honest. Another Frontiers article, this time in Neuroinformatics, found similarly steep drops when random-window evaluation was replaced with participant-disjoint testing, with balanced accuracy falling to roughly the low 60s or mid-50s depending on the disorder. Taken together, these papers suggest that the problem is not whether EEG-based classification can work at all, but whether the published numbers reflect true out-of-sample performance.
The new Frontiers Neuroscience study also points to a practical reason why some approaches are more vulnerable than others. Spectral features, such as band power, can encode stable individual traits alongside any disorder-related signal, making them particularly prone to shortcut learning when folds are mixed across the same child. Deep models trained end to end on raw EEG were more stable in this experiment, and the best-performing convolutional network preserved sensitivity even under the tougher protocol. The authors used SHAP, a feature-attribution method, to inspect what the network relied on and reported the strongest signals over frontal and central electrodes, a pattern they say is broadly consistent with existing ADHD EEG literature.
That interpretability result is important, but it should not be overstated. SHAP can show which channels a model weighs most heavily; it cannot prove biological causation. Still, the topography offers a degree of reassurance that the network is not simply keying off random noise. The authors also note that their raw-EEG model retained useful recall while remaining compact enough for faster training and inference than the hybrid recurrent alternative. In a field where many studies focus on boosting headline accuracy, the more important message may be the opposite: once leakage is removed, realistic performance is lower, but it is also more trustworthy.
For parents, caregivers and clinicians, the practical takeaway is straightforward. EEG-based ADHD tools may have promise as screening aids, but inflated validation methods can make them look ready for clinic before they truly are. The latest studies argue for more disciplined testing, clearer reporting and greater caution when interpreting headline accuracies. Subject-wise validation does not diminish the value of machine learning in paediatric neuroscience; it makes the results more credible, and therefore more useful.
Disclaimer: This content is for informational purposes only and is not intended to be a substitute for professional medical judgment, advice, diagnosis, or treatment.